
This course includes our updated coding exercises so you can practice your skills as you learn.
See a demo
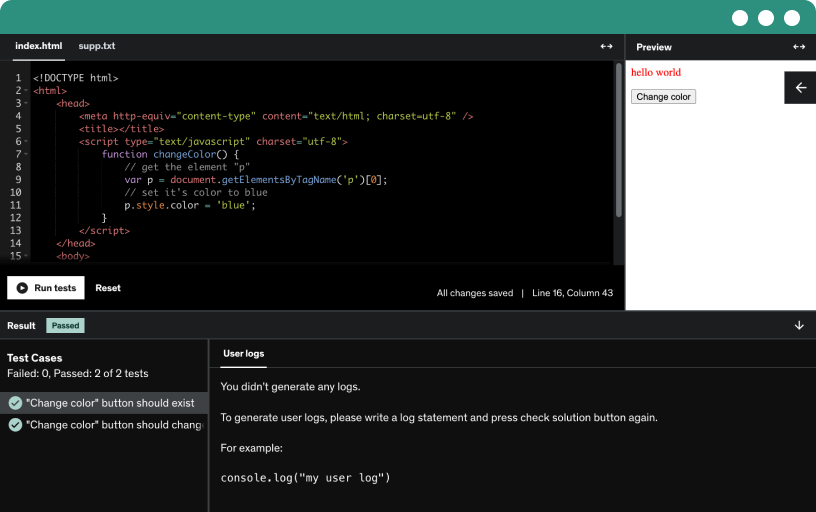
Learn through theoretical and practical classes, using a real-time listening test with text slides to reinforce the correlation test, and complete coding exercises after practical lessons.
Request a refund within Udemy's 30-day guarantee if the course doesn't meet your expectations, and unenroll with support's help.
Explore how machine learning enables computers to learn from data, discover patterns, and improve over time through supervised, unsupervised, and reinforcement learning, with applications like spam detection and recommendations.
Learn supervised regression models, from linear regression and ridge regression to SVM regressor, random forest regressor, and polynomial regression, focusing on least squares, robustness, and handling nonlinearity.
Explore supervised classification models like logistic regression with sigmoid outputs, SVM, KNN, random forest, and naive Bayes, learning how probabilities, margins, and nearest neighbors drive binary and multi-class tasks.
Explore unsupervised clustering, including K-means and DBscan, to form clusters, define centroids, distances, and densities, and discuss the elbow method and outliers.
Explore deep learning, a multi-layer neural network approach within machine learning, and learn how CNNs, feature extraction, and GPUs drive autonomous driving, image recognition, and large-scale data insights.
Explore artificial intelligence, its relationship to machine learning and deep learning, and how AI powers supply chains, voice assistants, autonomous vehicles, healthcare, and personalized experiences.
Explore how Python and R support data science tasks, highlighting Python's simple syntax, versatile libraries, and data visualization capabilities, along with R's statistical analysis strengths and visualization power.
Explore development platforms for data science, including Jupyter Notebook, Anaconda, Azure, and Google Colab, highlighting interactive live code, Conda environments, cloud options, and GPU/TPU access.
Prepare data by cleaning, manipulating, and transforming it into a clean, consistent format for machine learning and analysis, ensuring data quality and handling missing values.
Learn data modeling to structure data, define relationships and constraints, and create blueprints for databases that support accurate predictions, data integrity, and scalable analysis using statistical and machine learning approaches.
Evaluate model performance on unseen data using regression and classification metrics, including MAE, MSE, RMSE, R-squared, accuracy, precision, recall, F1 score, and AUC.
Learn how to deploy machine learning models in real-world settings, choosing between batch, real-time, cloud, edge, and container-based deployments, while prioritizing performance, security, and ongoing maintenance.
Learn how to evaluate machine learning models using classification and regression metrics, including accuracy, precision, recall, F1, confusion matrix, ROC AUC, MAE, MSE, RMSE, and R-square.
Master Python basics by exploring expressions and variables, operands and operators, and rules for naming variables, then apply assignment to store and reuse expression results.
Practice expressions and variables in Python by calculating eggs bought and used over three days. Assign daily values, sum totals, and compute remaining eggs with print statements.
Explore Python's core data types like int, float, str, and bool, and learn typecasting to convert between them with practical examples of memory use and operations.
Practice hands-on Python data types conversion through three problems: string to integer, float to string, and boolean to integer format, with type verification.
Explore Python string manipulation, including indexing (positive and negative), slicing and stepping, and length. Learn concatenation, escape sequences, upper and lower case changes, and replace operations.
Perform hands-on practice with Python string operations, including slicing, indexing, negative indexing, substrings, stepping, length, concatenation, escape sequences, case conversion, and replacement.
Learn about tuples and lists in Python, including immutable characteristics, concatenation, slicing, and nested tuples and lists. Master list operations such as append, insert, remove, and pop.
Engage in hands-on Python practice with tuples and lists, solving nested tuple and list slicing, index-based extractions, negative indices, step slicing, and list methods like append and remove.
Explore Python sets to guarantee uniqueness, learn to manipulate them with add, update, remove, discard, union, and intersection, and convert lists with the set function.
Learn to work with sets in Python using Jupyter Notebook: convert lists to sets to remove duplicates, add and remove elements, and perform union or intersection.
Explore Python dictionaries, their key value structure, unique immutable keys, and operations like add, delete, and slice with keys, along with methods keys, values, and items.
Practice working with Python dictionaries in a Jupyter Notebook, solving four problems: extract name and grade, add email, remove city, and display keys, values, and items.
Explore conditions and branching in Python, mastering boolean logic, control flow, and comparison operators (==, !=, >, <, >=, <=) using if, else, and elif to drive dynamic program decisions.
Apply Python conditionals and branching to classify animal speed, determine discounted tickets by age and height, and assess eco friendly race eligibility with nested if.
Explore Python loops for iteration, including for and while loops, using range and enumerate to repeat actions over lists or strings, and print values from 1 to 5.
Develop proficiency in loops by implementing for and while loops, using enumerate and f-strings to print, generate even numbers, and classify values into positive, negative, or zero.
Master functions as reusable blocks of code using def, parameters, return, and print, with examples of arguments and the dry principle alongside global versus local variables.
Build and apply three Python functions to compute compound interest, EMI, and BMI with automatic assessments, reinforcing practical function development for real-world tasks.
Explore how Python uses classes as blueprints to define objects with attributes and methods, using a car example and a calculator to show the init method, self, and object creation.
Explore building a Python library system by defining a book class with title, author, and availability, and implementing borrow, return_book, and check_availability methods to manage books.
Explore how an api acts as a messenger enabling apps to request data from servers via rest and http methods on endpoints, with stateless crud operations and request-and-response flows.
Learn the HTML structure and core tags, including doctype, HTML, head, body, headings, paragraphs, links, and tables, and use BeautifulSoup with Python for extracting links in web scraping.
Learn web scraping with BeautifulSoup and Pandas in a hands-on Python lab. Extract headings, paragraphs, links, and tables, then organize data into a data frame and export to Excel.
Learn how to use pandas in Python to read from csv and Excel, create data frames from dictionaries, inspect data with head and tail, and export to csv or Excel.
Load February sheet from an Excel file into a pandas dataframe and print the first ten rows; convert a dictionary to a dataframe and export as products.csv without indices.
Understand missing values in data, including mcar, mar, and na, and learn how deletion, simple imputation, or advanced techniques affect analysis and bias.
Identify missing values in a dataset using Python in a Jupyter notebook by applying isnull and sum across columns, printing a missing data report.
Identify missing values in the dataset using Python, and print a heading with per-column counts, noting income and city have five and three missing values.
Imputation replaces missing values with estimated data to preserve entries and maintain data integrity for models, using mean, median, mode, or domain-based methods while addressing different missing data types.
Learn how to impute missing values using sklearn's SimpleImputer, choosing mean or median for numeric data and the most frequent value for categorical data, with practical code examples.
Learn how to impute missing values using sklearn's simple imputer, applying median for income and most_frequent for city, with fit and transform steps.
Identify and apply the correct dataframe data types in Python, such as int64, float64, object, bool, and datetime64, to optimize memory, maintain data integrity, and enable accurate analysis.
Explore how to derive and assign correct data types for every column, preventing incorrect insights by using Python methods to convert values to int, float, or other types.
Inspect and correct dataframe data types in Python, converting columns like customer lifespan to integer and date of purchase to datetime with astype, addressing inconsistencies for reliable analysis.
Explore inconsistent values in data entries that defy standard formats, causing inaccurate analysis and flawed models; learn detection, normalization, mapping, and validation to prevent and fix them.
Learn to identify and handle inconsistent data in Python by extracting unique values from a column, distinguishing real from inconsistent entries, and filtering out unwanted rows to preserve data integrity.
Apply the unique values method to identify the inconsistent value in the customer lifespan months column. Remove the inconsistent value by filtering the data.
Identify and handle full and partial duplicates in datasets, understand their impact on analysis, reporting, and model accuracy, and apply practical detection and prevention methods.
Identify and remove duplicate customer records in a Python data cleaning workflow, using duplicated() to locate duplicates and drop_duplicates(inplace=True) to ensure unique data.
Identify duplicates in your dataset, filter them, and remove duplicates using drop_duplicates with inplace set to true, then verify no duplicates remain.
Explore data sorting and ordering, covering ascending and descending formats for numbers, dates, names, and text, and learn how sorted data improves readability, ranking, and analysis in dashboards and reports.
Learn to sort data in Python using sort_values by a column and order. Explore ascending true and descending false to control sort direction, storing results in sorted_data.
Sort the dataset by customer income in descending order using Python's sort_values, illustrating how to rank data by the income variable from highest to lowest.
Explore data slicing, selecting specific rows, columns, or values to narrow analyses, create tailored views, and prepare training and testing periods for machine learning models.
Learn to filter data in Python using dot log and dot ilock methods, define ranges for rows and columns, and understand zero-based indexing and iloc's exclusion of last value.
Explore how to slice data with dot loc and dot iloc methods to retrieve the first five rows and the columns from customer ID to region for analysis.
Filter data by selecting rows that meet conditions to focus on relevant information, excluding the rest, and preparing data for grouping, statistics, or visualizations (unlike sorting, which reorders data).
Learn to filter data in Python using conditional operators, deriving column values and applying or and and logic to select records, such as ages above 25 or between 20 and 50.
Filter the data using conditional operators to select male customers, then refine by purchase frequency above five and customer lifespan between 2 and 5 months with and logic.
Merge data from sources by joining on keys to enrich analysis and create a single source of truth, using inner, left, right, and full joins while avoiding duplicates and nulls.
Learn to merge two datasets in Python using pandas' merge on a common column such as customer ID, choosing inner, left, right, or outer joins.
Merge performance data with the customer dataset by loading the performance file, performing an inner merge on customer ID, and previewing the joined data with recency, frequency, and monetary scores.
Learn to join datasets by position with vertical stacking or horizontal alignment, using concatenation to append batches or add features, without requiring matching keys, and differentiate it from merging.
Learn to vertically concatenate datasets in pandas using the concat method not based on a common column. Create a concatenated_data variable and inspect results with head and shape.
Learn to concatenate additional data vertically with pandas, load from Excel, view with head and tail, and clean results by resetting the index and dropping duplicate columns.
Generate new features from existing data to boost model performance through transformations, ratios, aggregations, date time decomposition, and encoded categorical features, while guarding against leakage and improving interpretability.
Learn feature engineering with customer data by creating new features, such as total purchase amount and customer lifetime value (CLV), using Python and domain knowledge.
Derive customer_value by multiplying frequency of purchases with the average purchase amount from pre-processed data, then compute CLV using customer lifespan in months in Python.
Extract date elements to reveal time-based patterns and seasonality, boosting model accuracy by converting dates into meaningful parts like year, month, day, weekday, and hour.
Extract year, month, and day from a datetime variable using Python to create new features and add them as columns for improved predictive modeling.
Extract year, month, and day from the date of purchase by ensuring date time types, deriving components in the preprocessed data, and dropping the original date of purchase column.
Explore feature encoding methods, including label, one-hot, ordinal, and binary encoding, to convert categorical variables into numeric form for machine learning models.
Apply level encoding to convert ordinal categories into numeric values using scikit-learn's level encoder, with churn status encoded as 1 for yes and 0 for no.
Encode the churn status by importing scikit-learn's label encoder, fitting and transforming the preprocessed data to convert yes/no into 1/0 for a classification model.
Apply feature binding to group continuous values into bins, simplifying data, capturing non-linear relationships, reducing outlier impact, and improving interpretability through equal width, equal frequency, and custom options.
Learn to convert numeric variables into categorical features using pd.cut, creating a bind_column with defined bins and levels, including lowest, and preview the first five rows.
Apply feature binning to create an engagement level from customer lifespan in months using pd.cut, with bins for low, moderately engaged, and highly engaged customers.
Learn how feature mapping transforms raw features into model-friendly representations, improving learning efficiency, accuracy, and generalization by using value, ordinal, polynomial, and interaction mappings.
Create a mapping dictionary to encode ordinal categories into numeric values, load it into a variable, and apply the map to a column to derive encoded ordinal features.
Create a dictionary to map engagement levels and apply the Python map method to a preprocessed data column, assigning 1, 2, and 3 to low, moderately engaged, and highly engaged.
Translate categorical features into numbers with dummy variables created via one-hot encoding, enabling models to detect presence or absence while avoiding multicollinearity by dropping a baseline.
Learn to convert categorical features into numeric dummies using pandas get_dummies, handling non-ordinal categories, and concatenate the results back into the dataset for machine learning.
Generate dummy variables for four categorical features—gender, city, region, and purchase channel—using pandas get_dummies and pd.concat to add the dummy variables to the preprocessed data along axis=1.
Explore kernel density estimate plots to visualize the distribution of a continuous variable, comparing KDE with histograms, and learn how to detect normality, skewness, and multimodal patterns.
Learn to visualize the distribution of numeric variables with kernel density estimates (KDE) plots in Python, including multi-variable KDE plotting using seaborn and matplotlib subplots.
Explore kde plots of age and average purchase amount, creating a two-panel figure and labeling each plot while assessing normality with Shapiro-Wilk.
Explore the Shapiro Wilk test for assessing normality, interpreting the W statistic and p value, testing the null hypothesis, and limitations with large samples.
Calculate Shapiro-Wilk test statistics to assess normality for numeric variables, import Shapiro from scipy.stats, and apply it to each numeric column, storing p-values in a Shapiro_results dictionary.
Apply the Shapiro-Wilk test to numeric columns to assess normality, interpret p-values for age and average purchase amount, and learn to import SciPy's Shapiro function in Python.
Explore data transformation methods to stabilize variance and reduce skewness for data closer to a normal distribution. Learn square root, log, and Box-Cox transformations and when to apply them.
Learn to transform skewed numeric data using square root, logarithmic, and Box-Cox methods in Python, applying to the age variable with Shapiro-wilk tests and CDF plots.
Apply square root and logarithmic transformations to numeric data, assess normality with the Shapiro-Wilk test and p-values, visualize with KD plots, and explore Box-Cox and Yeo-Johnson transforms.
Identify the target and features, ensuring correct selection for accurate predictions. Use domain knowledge and statistical tests, including correlation and chi-squared, to select features and avoid leakage and multicollinearity.
Learn to separate features (x) and the target (y), drop unnecessary columns and dummy variables to remove redundancy, and prepare data for efficient machine learning model development.
Select features by dropping irrelevant columns from processed data and prepare two feature sets for regression and classification: x_rec and y_rec for CLV; x_class and y_class for churn status.
Learn feature scaling to bring numeric features to a similar range, using min-max and standard scalers to improve convergence and fair contribution for KNN, SVM, and neural networks.
Learn to scale features in Python using standard scaler and min max scaler, importing from sklearn.preprocessing, applying fit_transform to prepare features for machine learning models, including classification.
Scale regression features with StandardScaler and fit_transform to produce scaled x_reg values. Scale classification features with MinMaxScaler, then round results with Python's round to achieve values between 0 and 1.
Learn principal component analysis to reduce dimensionality by transforming correlated features into uncorrelated principal components that capture most variance, speeding up models and simplifying visualization.
Apply principal component analysis to reduce feature dimensionality using scikit-learn's PCA, and identify the optimal number of components with the explained variance ratio plot.
Apply principal component analysis to reduce dimensionality, compute explained variance ratio, and visualize how a single component can explain nearly 100% of variance, with caution for features count.
Split a dataset into train and test sets to evaluate generalization and prevent overfitting. Use common ratios like 80/20 or 70/30 and fix a random state for reproducible splits.
Split into train and test sets with sklearn's train_test_split, creating x_train, y_train, x_test, y_test, using test_size 0.2 and random_state 42, scale features then train and evaluate model on test set.
Execute train_test_split and scale features for regression and classification models with 20% test data and random_state 42, preparing x and y sets for pre-processing before predictive analytics.
Defines a matrix as a grid of numbers with rows and columns, explains indexing and types, and covers addition, subtraction, scalar and matrix multiplication, with applications in graphics and data.
Compare scalars and vectors by showing scalars as magnitude-only numbers and vectors as quantities with magnitude and direction, using arrows and ordered pairs for addition and scalar multiplication.
Explore linear algebra, studying vectors, matrices, and linear transformations. Uncover how solving systems of equations, matrix operations, and eigenvalues and eigenvectors drive computer graphics and machine learning.
Discover how tensors generalize scalars, vectors, and matrices into higher dimensions, and master their order, shape, and axes for handling multi-dimensional data in deep learning.
Understand how to transpose a matrix by flipping rows and columns, denoted A^T. Learn key properties like transpose of a transpose, and sums and products in machine learning.
Explore how the dot product drives matrix multiplication by pairing rows with columns, summing products, and producing a new matrix with dimensions. Recognize the dimension matching rule and key properties.
Explore how linear regression fits a best straight line by minimizing the rss to predict a continuous target, using slope and intercept with closed-form or gradient descent.
Build a Python linear regression model with scikit-learn to predict customer lifetime value, train with X_train and y_train, predict with X_test, and evaluate with mean squared error.
Build a linear regression model with scikit-learn, train on feature and target data, predict on test data, and compare models using mean squared error while plotting predicted vs actual outcomes.
Explore how logistic regression handles binary classification by mapping input features to probabilities with the sigmoid function, thresholding at 0.5, and training via cross-entropy loss and gradient descent.
Apply logistic regression to predict churn status from features using train and test data; train the model, predict outcomes, and evaluate with accuracy score and a confusion matrix heatmap.
Build a logistic regression classifier with scikit-learn, train on X_train and y_train, evaluate with accuracy_score and confusion_matrix, and visualize results with a seaborn heatmap.
Explore how k-means clustering partitions data into k centroids using Euclidean distance, minimizes intra-cluster variance and WCSS, and uses the elbow method to choose the optimal k.
Learn to perform K-means clustering in Python to segment customers, import from scikit-learn, compute within-cluster sum of squares, and use the elbow method to choose the optimal number of clusters.
Apply k-means clustering to customer data using recency, frequency, and monetary scores; determine optimal clusters with the elbow method, label clusters, and compare averages to identify loyal versus regular customers.
Explain how decision tree regression predicts continuous targets by recursively splitting feature space into regions with a mean value. Highlight impurity, MSE, pruning, and stopping criteria to prevent overfitting.
Use scikit-learn's decision tree regressor to train (fit) on features and outcomes, predict test data, and evaluate with mean squared error for customer lifetime value.
Train a decision tree regressor from sklearn, evaluate it with mean squared error on train and test data, and compare predicted versus actual outcomes.
Discover how decision tree classification splits data to form pure leaves using Gini impurity or entropy and information gain, offering non-linear decision boundaries and easy interpretability as a white-box model.
Learn to build a decision tree classifier to predict customer churn, train the model, and evaluate it with accuracy score and confusion matrix, and visualize results with a heat map.
Develop a decision tree classification model using sklearn, train and test data, evaluate with accuracy score and confusion matrix, and compare its performance to logistic regression.
Explore how random forest regression, an ensemble method, predicts continuous targets by averaging outputs from many decision trees, using bagging and random feature selection to reduce overfitting and improve generalization.
Apply the random forest regressor in Python to train an ensemble of decision trees, make predictions, and evaluate with mean squared error for customer lifetime value.
import and train a random forest regressor from sklearn, evaluate with mean squared error, compare with linear regression, and predict customer lifetime value from test data.
Ensemble multiple decision trees into a random forest to improve classification accuracy. Train on bootstrapped samples with random feature subsets, and use majority voting for final predictions, reducing overfitting.
Apply the random forest model to predict customer churn. Import from sklearn.ensemble, fit on train data, predict test data, and evaluate with accuracy score and a confusion matrix heatmap.
Explore hands-on random forest classification with sklearn, including training, predicting, and evaluating accuracy and confusion matrix for churn prediction, and compare with logistic regression, achieving around 85% accuracy.
Master the End-to-End Machine Learning Process with Python, Mathematics, and Projects — No Prior Experience Needed
This course is not just another introductory tutorial. It is a complete and intensive roadmap, carefully crafted for beginners who want to become confident and capable Machine Learning practitioners. Whether you're a student, a job-seeker, or a working professional looking to transition into AI/ML, this course equips you with the core skills, hands-on experience, and deep understanding needed to thrive in today’s data-driven world.
Why This Course Is Different
This masterclass solves both problems by following a clear, layered, and project-oriented curriculum that blends coding, theory, and practical intuition — so you not only know what to do, but why you're doing it.
You’ll go step-by-step from foundational Python to building real ML models and deploying them in real-world workflows — even touching advanced topics like ensemble models, hyperparameter tuning, regularization, and generative AI.
What You’ll Learn — Inside the Masterclass
#______Foundations of Machine Learning and Artificial Intelligence
What is ML, how it differs from AI and Deep Learning.
Key ML model types: Regression, Classification, Clustering.
Understanding AI applications, Gen AI, and the future of intelligent systems.
Knowledge checks to reinforce conceptual understanding.
#______Python Programming from Scratch – for Absolute Beginners
Starting with variables, data types, conditionals, loops, and functions.
Data structures: Lists, Sets, Tuples, Dictionaries with hands-on labs.
Object-oriented programming, API requests, and web scraping with BeautifulSoup.
Reading and writing real-world datasets using pandas.
#______Data Cleaning and Preprocessing – Real-World Essentials
Handling missing values, data types, inconsistencies, and duplicates.
Sorting, slicing, filtering, merging, and concatenating datasets.
Performing these operations with structured labs and real datasets.
#______Feature Engineering – Turning Raw Data into Intelligence
Generating new features from date/time and domain knowledge.
Encoding categorical variables, binning, mapping, and generating dummies.
Prepping datasets to enhance model performance.
#______Exploratory Data Analysis (EDA) and Visualization
Creating distribution plots using KDE.
Checking for normality with Shapiro-Wilk tests.
Performing data transformations (Log, Sqrt, Box-Cox).
Selecting meaningful features and reducing dimensions via PCA.
#______Mathematics for Machine Learning – Build True Intuition
Linear Algebra: Vectors, Matrices, Dot Product, and Transpose.
Understanding tensors and their applications in deep learning.
Grasping the math behind model architecture and training logic.
#______Machine Learning Algorithms – Explained and Built from Scratch
Linear Regression, Logistic Regression, KMeans Clustering.
Decision Trees, Random Forests (Regressor & Classifier).
Building models line-by-line in Python with evaluations and predictions.
Working with real datasets in guided hands-on labs.
#______Advanced Boosting Algorithms – The Industry’s Favorites
AdaBoost, Gradient Boosting (GBM), CatBoost, LightGBM, and XGBoost.
Step-by-step breakdown of how these models work and how to train them.
Understanding when and why to use each one.
#______Model Evaluation, Optimization, and Improvement
K-fold cross-validation, L1 & L2 regularization.
Oversampling & undersampling methods (SMOTE, Tomek Links).
Hyperparameter tuning using GridSearch, RandomSearch & Bayesian methods.
Making your models more robust, fair, and generalizable.
#______Deep Learning Fundamentals with TensorFlow 2.0
Understanding how neural networks learn.
Layers, activation functions, weight initialization (Glorot), and SGD.
Preprocessing data, training neural nets, evaluating and improving DL models.
#______Introduction to Generative AI and Prompt Engineering
AI workflow, types of AI, and Gen AI applications in NLP, vision, and speech.
Prompt engineering: what it is, how it works, and real-world best practices.
Projects like building a chatbot with LLaMA and generating images using Stable Diffusion.
#______Hands-On Real Projects – From Scratch to Deployment
Real-life ML tasks including classification and regression case studies.
Deep learning projects: text-to-image generation and chatbot development.
Walkthroughs of full ML pipelines: cleaning, modeling, evaluating, and presenting results.
Building portfolios worthy of recruiters and hiring managers.
What You’ll Walk Away With
By the end of this course, you’ll have the ability to:
Write clean Python code for machine learning projects.
Understand and explain how various ML algorithms work.
Perform data cleaning, EDA, feature engineering, and model training.
Evaluate and fine-tune models using advanced techniques.
Work on real ML projects that simulate professional work environments.
Understand deep learning fundamentals and generative AI workflows.
Build a portfolio that can help you land entry-level to intermediate ML jobs or freelance gigs.
One Honest Note
This course emphasizes real understanding, not animated fluff. Lessons are code-first, explanation-rich, and designed for learners who want depth, not shortcuts. If you’re ready to invest the effort, the rewards are real.
Final Thought: Your Transformation Starts Here
Machine Learning is not just a hot trend — it’s the future of decision-making, automation, and innovation. But mastering it takes commitment.
This 2025 Machine Learning Masterclass will guide you through that journey step-by-step — helping you not only learn ML, but think like an ML practitioner, and work like one too.
Join now and start your transformation into a Machine Learning expert.